Perplexity launches Orchestrator, an API to use models from several labs with a single account
IA en un minuto newsroom · Editor: Jon Elgezabal
In 30 seconds
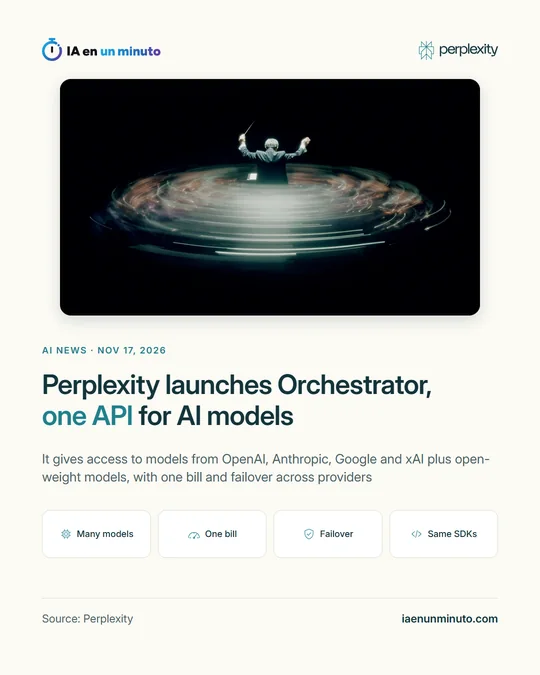
Perplexity is opening Orchestrator to developers as a single gateway to closed models from Google, OpenAI, xAI and Anthropic and to open ones like GLM, Kimi or DeepSeek. Perplexity bills everything on one invoice, with no surcharge on credits, and moves a request elsewhere when a provider fails. Routes and Auto effort, still in testing, decide which model takes each task and how hard it thinks.
On Tuesday, November 17, Perplexity unveiled Orchestrator, a developer API that puts models from Anthropic, xAI, OpenAI and Google behind one point of access, together with open-weight options such as DeepSeek, Kimi and GLM. The open-weight ones run either on Perplexity's own infrastructure or with inference partners.
The company sets out the background: working with several labs usually means keeping separate contracts, accounts, keys, invoices and security reviews. On top of that, so far this year labs including OpenAI and Anthropic have put out more than a dozen new models, while over 100 open-weight ones have been released.
Orchestrator works with three request formats, OpenAI Chat Completions, OpenAI Responses and Anthropic Messages, so teams can keep their usual SDKs. Perplexity says most of them only need to swap the API key and base URL and pick one of the models on offer.
All supported models come under a single provider and a single invoice, and Perplexity adds no platform fee on top of credits. The API console lets teams follow usage and spending, with separate keys per project or team, and administrators can decide which models are allowed, restrict users, cap spending and request capacity.
The service watches each provider's health, capacity and latency to spread traffic among those responding best and, when a request fails, it can send it again to another deployment of the same model, without teams having to code that logic.
Two more features arrive in preview. Routes lets developers explain, in everyday words, what kind of request goes to each model and pick a default one, starting from lower-cost, balanced or higher-quality profiles. Auto effort tunes how much a supported model reasons on its next turn, following a policy set by the developer. The post gives no per-model prices.
Why it matters · analysis and opinion
What Perplexity is selling is not a model but the layer that decides which one to use. For a team already mixing providers, the saving lies less in the price per request than in no longer handling scattered contracts, keys and invoices, and in not writing its own backup system. The trade-off is plain: all that traffic now depends on one more intermediary, with its own outages and terms. Building compatibility on OpenAI and Anthropic formats lowers the cost of trying it, because going back is easy too. The newest piece, splitting requests from a description in words, is still in preview, so it is worth measuring against real workloads before trusting it with production traffic.
Official source: Perplexity · Written with the help of AI: how we make the news